The database you already run. The data product you haven’t built yet. One standard way to connect to both.
Proxy existing database drivers or build an ADBC service for anything your code can reach. Write it in Rust, Go, Python, or TypeScript. You define the query; Apache Arrow carries the results.
Existing databases New data services↓ One ADBC interface
New to ADBC? Start here.
A common way to connect. Data ready for analytics.
ADBC stands for Arrow Database Connectivity. It is an open standard from the Apache Arrow project for connecting applications to databases. Like ODBC or JDBC, it gives developers a familiar set of operations: connect, run a query, and read the results.
ADBC is built around Apache Arrow: a format that organizes data into typed columns. Results arrive in batches that analytical tools and data frames can consume efficiently, reducing the need for format conversions.
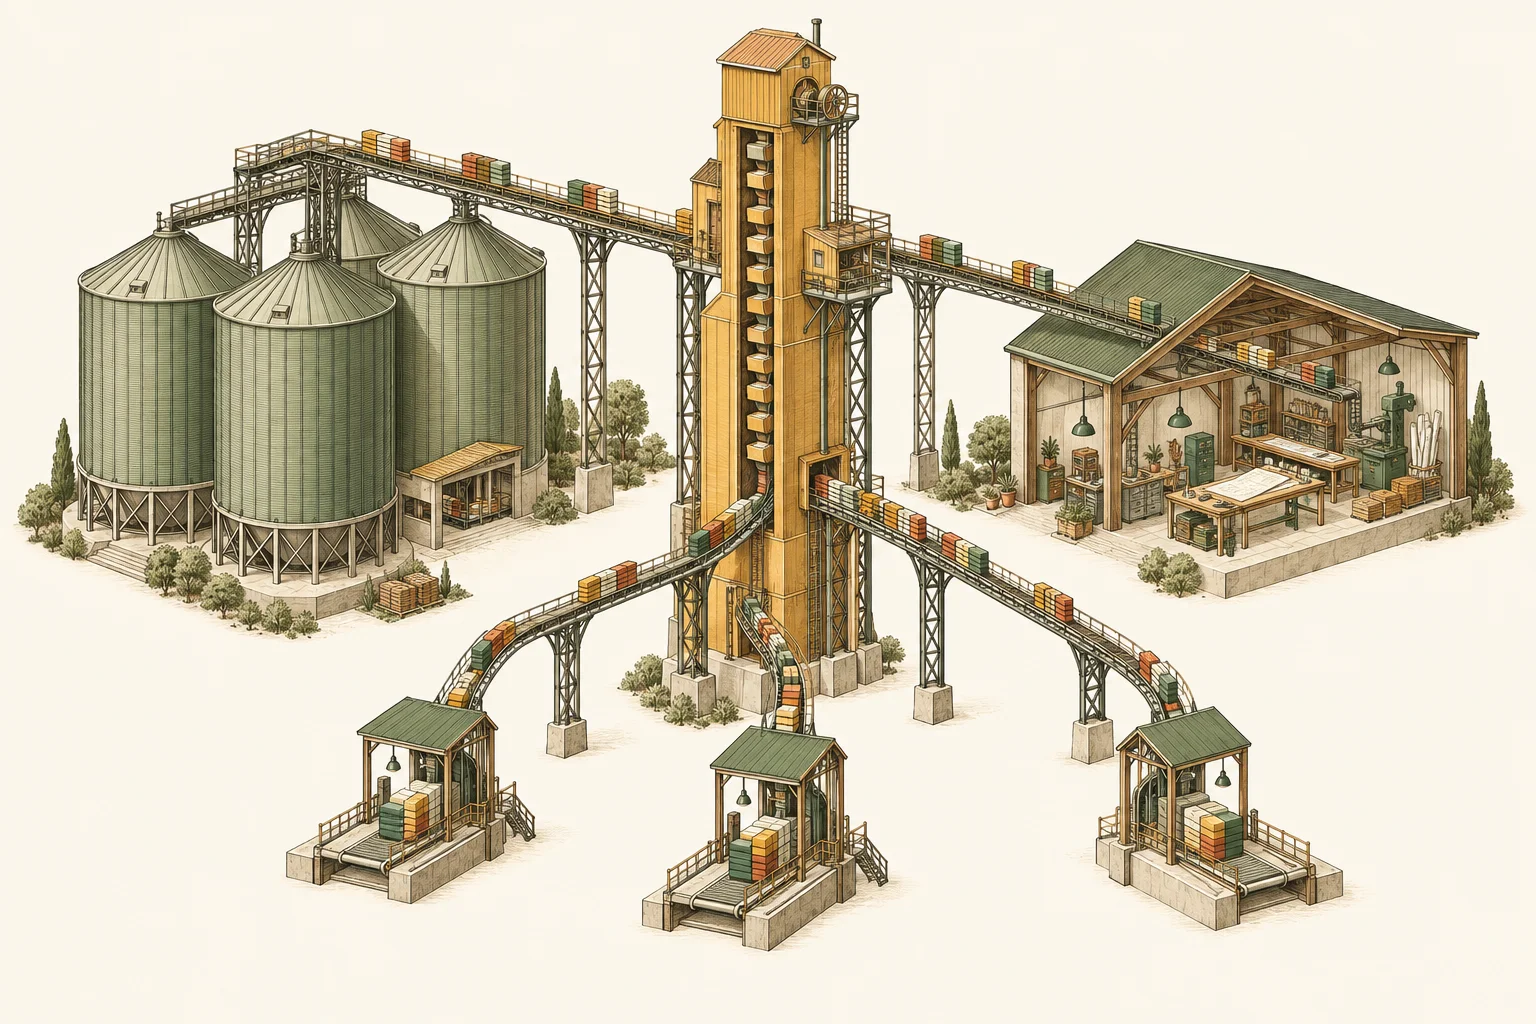
Grainlift brings that interface to your service or idea. ADBC drivers typically connect to databases. Grainlift can proxy those connections—or let you build a service that behaves like an ADBC driver to its clients, backed by anything your code can reach.
Existing databasePostgreSQL · DuckDB · SQLite · more
BUILD A NEW DATA SERVICE
Your Grainlift service
Built with a Grainlift framework
Authentication · sessions · limits · cleanup
Rust · Go · Python · TypeScript
↓
Your code, your dataAPIs · files · models · business logic
Follow a request down either path, then an Arrow batch back to the client. Results are pulled one batch at a time.
01 / PROXY
Turn installed drivers into shared infrastructure.
Run downstream drivers and their dependencies once on the service. Give applications a named, authorized target. Keep database credentials and configuration under central control.
Anything your code can reach. An ADBC interface to it all.
Connect to APIs, files, models, proprietary systems, or your own business logic. Your service interprets the request and returns Arrow batches through the Grainlift driver. Grainlift handles the connection and result lifecycle; no downstream database is required.
Database drivers usually interpret a query as SQL. In a custom Grainlift service, your backend decides how to interpret the statement text: SQL, a domain-specific expression, a command, or a natural-language request.
You implement the parser, routing, or model call. The application still executes a statement through ADBC and reads typed Arrow results.
Fetch a market-data APIReturn symbols, prices, and timestamps
Forecast next week→
Run your forecasting modelReturn dates and predicted values
The API and forecast requests illustrate services you could build. Your backend defines their syntax and behavior. Tools that generate SQL need a backend that understands that SQL.
What this enables
Less integration work. More places your data can go.
One integration for your customers.
Deliver your data product through a standard ADBC connection. Customers can consume Arrow results in their applications and pipelines.
A shared access layer for your teams.
Centralize database drivers, credentials, and target permissions. Keep native driver installations out of every notebook, job, and application image.
A path from useful code to useful service.
Put your pricing logic, research dataset, or model outputs behind an ADBC interface. Implement the queries and capabilities your backend can actually support.
Your language. Their database interface.
Write the service. Grainlift brings the plumbing.
Frameworks in four languages share the Grainlift contract. Define what a request means and where its data comes from; reuse authentication, handle ownership, bounded results, and cleanup.
You writeQuery behavior & Arrow results
→
Grainlift providesADBC service lifecycle over VGI-RPC
→
Your users getAn ordinary ADBC connection
Rust
Build on the native server library.
Implement Grainlift’s Backend, BackendConnection, and BackendStatement traits.
The Rust path reuses the Grainlift server library; Go, Python, and TypeScript have dedicated backend frameworks. Start from the source repositories and runnable examples. The TypeScript package is prerelease and not yet on npm; Python package publication is a separate release step.
Go supports HTTP, HTTPS, loopback TCP, mTLS TCP, and Iroh with the published VGI-RPC Go v0.30.0 dependency. Iroh requires a separately installed VGI Iroh bridge. See each framework’s repository for transport setup and requirements. Your backend implements SQL behavior, transactions, and other capabilities; unsupported operations return ADBC NOT_IMPLEMENTED. The frameworks do not supply a general SQL engine.
Measured, not imagined / EC2 · 26 Sep 2026
Real queries. Recorded results.
Database proxy throughput and custom-service latency, measured through the native ADBC driver. Select a workload to see the numbers in context.
3,349.6
queries / second
DuckDB through Grainlift · HTTP
32 concurrent sessions 2,048 verified rows per query
THROUGHPUT / QUERIES PER SECONDHigher is better →
DuckDB3,349.6
p99 latency 17.5 ms
PostgreSQL1,130.0
p99 latency 35.3 ms
SQLite1,064.4
p99 latency 32.2 ms
01,7503,500
The workload. A 200,000-row dataset; 2,048 rows and a 128-byte payload per row returned and verified on each query. Each of 32 independent sessions ran two warmups and 50 measured iterations. One short run per backend over HTTP.
The environment. Client, server, and databases on the same EC2 host: 48 ARM Neoverse-N1 CPUs, 92.6 GiB RAM, Amazon Linux 2023. DuckDB 1.5.5; SQLite and PostgreSQL ADBC drivers 1.12.0; PostgreSQL 14. No query errors in these runs.
4,096 verified rows per query 8 Arrow batches · no SQL engine
MEAN QUERY LATENCY / MILLISECONDS← Lower is better
TCP / mTLS3.82 ms
Per-run p99 range 4.18–5.26 ms
HTTP10.09 ms
Per-run p99 range 10.76–16.18 ms
0612 ms
The workload. A synthetic Rust service returns 4,096 rows with 64-byte payloads in eight 512-row batches. One reused ADBC connection; ten warmups, 1,000 measured queries, and 100 expected errors per run. Means average three repetitions; successful-query latency excludes expected errors and initial connection setup.
The environment. Same-host EC2 loopback, 48 ARM Neoverse-N1 CPUs, 92.6 GiB RAM, Amazon Linux 2023. Release Rust build, verified mTLS, and bounded result connection reuse. No downstream database. All reported cases passed with zero unexpected errors.
These are different workloads, not a proxy-versus-framework comparison. Same-host measurements do not establish WAN performance or production capacity. There is no direct-ADBC baseline here. Go and TypeScript performance is not represented by these results.
Grainlift + VGI / Complementary by design
Shared roots. Different ways to grow.
Grainlift and VGI are complementary products, built for different ways of using data. You can use both in the same platform.
Grainlift gives applications a standard ADBC connection to databases and custom services. VGI extends DuckDB and Haybarn with remote tables and functions that participate in SQL queries.
They share VGI-RPC and Apache Arrow underneath. That common foundation supports both database-style access from applications and custom capabilities inside a query engine.
Choose the interface your users already work with.
Your goal
Grainlift
VGI
Reach your users
Connect notebooks, applications, and pipelines through an ADBC driver.
Let DuckDB and Haybarn users query remote tables and call functions from SQL.
Expose your backend
Proxy an existing database driver, or interpret requests in your own data service.
Build a worker that exposes data and computation through VGI’s table and function interfaces.
One business capability. Two ways to use it.
A pricing team could expose its engine through Grainlift for applications that submit pricing requests, and through a VGI worker for analysts who call a pricing function inside a DuckDB query. Both implementations can reuse the team’s underlying pricing logic.
Each interface needs its own implementation. Sharing VGI-RPC does not make a Grainlift endpoint a VGI catalog, or make a VGI worker an ADBC service. Grainlift does not require DuckDB.
What will you connect next?
Your data. Their next connection.
Put an existing database behind Grainlift, or build the service only your team can build.
Sessions, transactions, and cursors belong to one server process. Replicas need session affinity; restarts invalidate sessions. Driver capabilities and cancellation vary. Writes are not automatically replayed after connection loss.
Apache Arrow, Arrow, Apache Arrow ADBC, ADBC, and the Apache Arrow logo are trademarks or registered trademarks of The Apache Software Foundation in the United States and other countries.